
Introduction to Python for Actuaries
Wednesday, November 4th, 1:00PM - 2:00PM EST
The ability to work in Python used to be an attractive actuarial quirk with highly specific applications. Now, Python is used every day to build rate models, analyze large data sets, automate reports and rate filings, and reduce exhausting analyses to a few simple sentences. Basic Python knowledge is frequently a hiring requirement, and the number of roles without it is shrinking. Fortunately, basic Python is easily acquired and immediately useful.
This lesson introduces the fundamentals of Python analysis in an actuarial context. In the course of one hour, attendees will write their own code to upload a csv of data, extract critical measures, and create visual exhibits. The workshop is appropriate for all actuaries and actuarial students, as well as anyone who works in a role that requires analysis or automation.
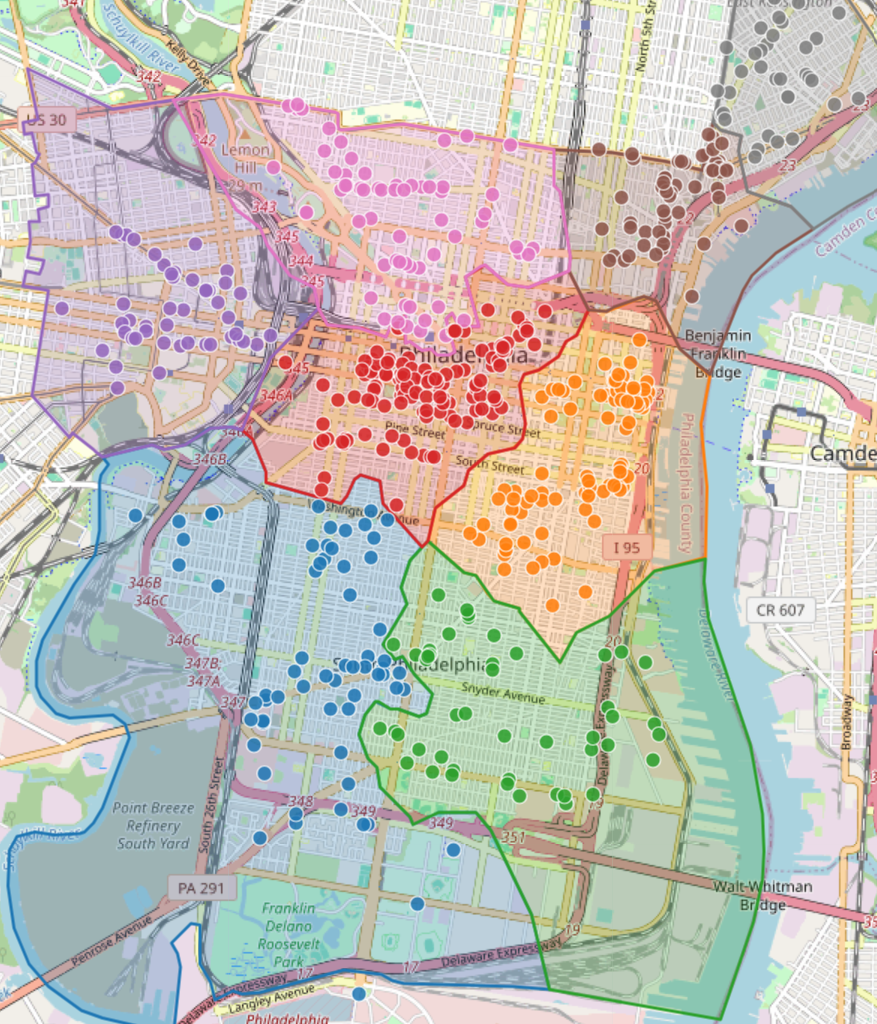
Data Science for Actuaries - Clustering Methods
Wednesday, December 9th, 1:00PM - 2:00PM EST
Actuaries are frequently faced with risk characteristics that carry meaningful signal but are too granular to be used as individual levels. To simplify models and improve credibility, these levels must be combined into cohorts whose risk characteristics are similar within but distinct between groups.
Clustering is an unsupervised machine learning method for identifying and defining these groups, from the optimal number of clusters to rulesets for assigning future unseen members. In this workshop, we’ll use Philadelphia restaurants to examine the mechanics of k-means and spatial ward clustering, including model diagnostics, and extensions such as Voronoi diagrams and geographical weights.
The work will be completed within interactive Excel and Jupyter Notebook files which will be shared with participants to follow along at home.